MentorAI Fine-Tuning Pipeline
LLM Engineering
 Source Code
Overview
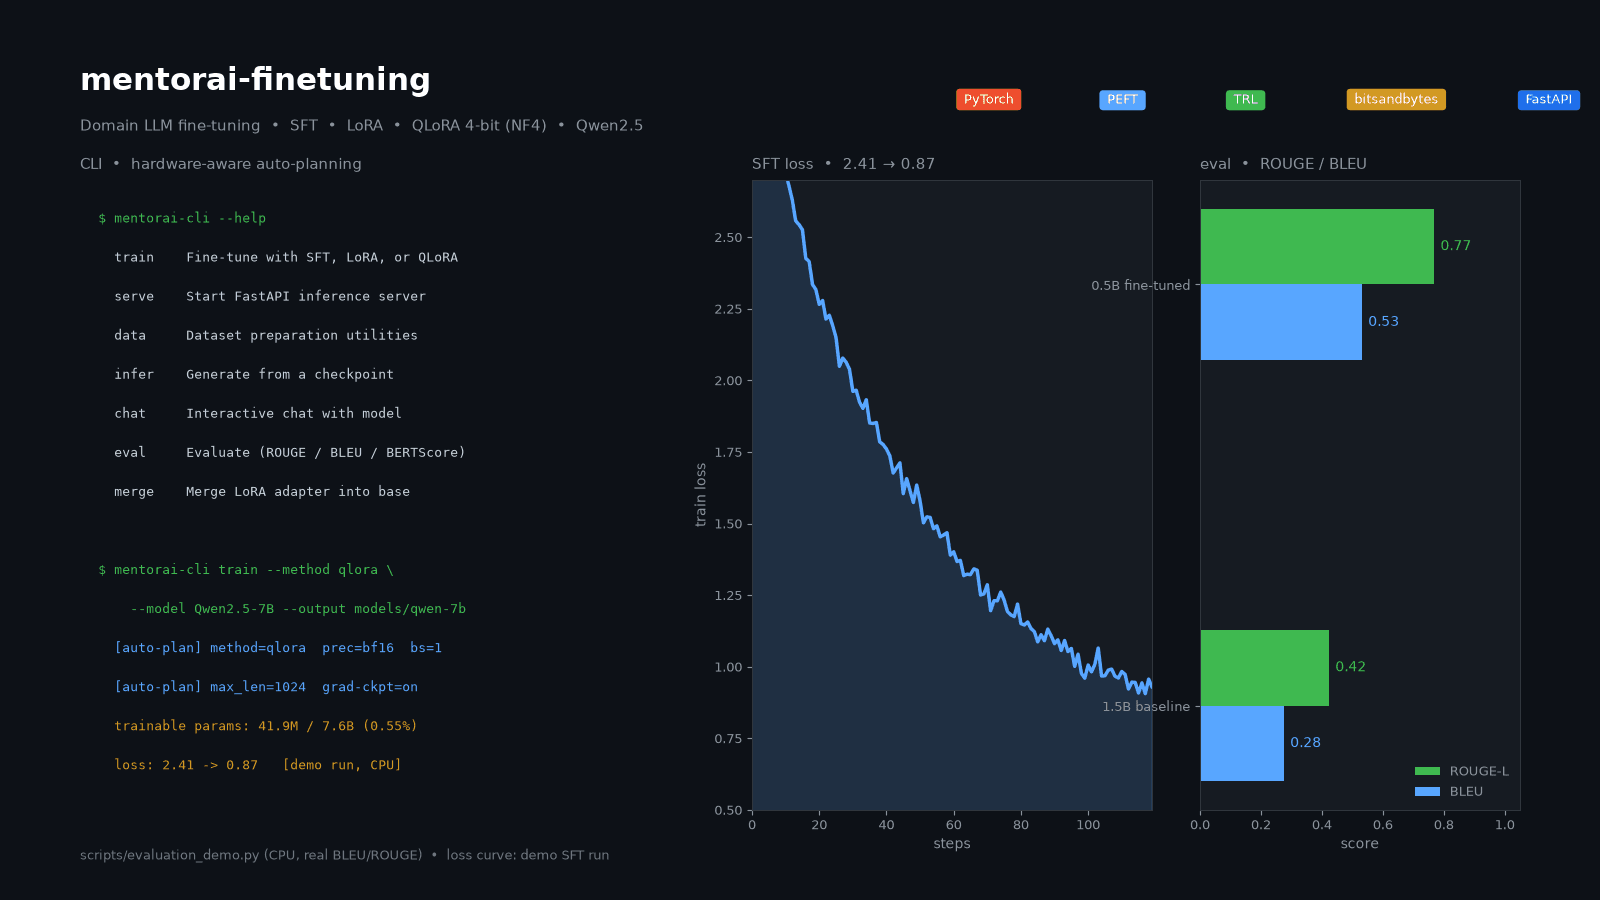
The MentorAI Fine-Tuning Pipeline is a standalone Python package (mentorai-finetuning) providing a reproducible pipeline for adapting Qwen2.5-0.5B/7B-Instruct to domain-specific tasks. It supports SFT, LoRA, and QLoRA via a unified CLI (mentorai-cli) with hardware-aware auto-planning that detects available GPU/CPU resources. The pipeline handles dataset engineering (Alpaca, ChatML, ShareGPT formats), tokenization, training with PEFT + TRL + Accelerate, and evaluation using ROUGE, BLEU, BERTScore, sacrebleu, and LLM-as-Judge. Training is tracked with MLflow. Adapters are merged and exported as Safetensors, served via a FastAPI inference server that feeds MentorAI's RAG pipeline.
Problem & Solution
No reusable, production-ready pipeline exists for fine-tuning open-source LLMs on domain-specific data — every project starts from scratch.
Standalone Python package (mentorai-finetuning) with CLI that automates the full cycle: raw documents → knowledge extraction → instruction dataset → QLoRA/LoRA fine-tuning → adapter merge → evaluation → FastAPI inference.
Architecture & Dataflow
Technical Stack & Implementation
AI / ML & Models
- Qwen2.5-0.5B/7B-Instruct
- PyTorch
- HuggingFace Transformers
- PEFT / QLoRA / LoRA
- TRL
- BitsAndBytes
- Accelerate
- MLflow
Backend & APIs
- FastAPI
- Python
- mentorai-cli
Data & Storage
- Datasets (HuggingFace)
- Pandas
DevOps & Infra
- Docker
- CUDA
Technical Challenges & Solutions
Generating high-quality instruction-answer pairs from raw domain documents
Preventing catastrophic forgetting while improving domain performance on a 0.5B model
Hardware-aware auto-planning that gracefully handles varying GPU memory constraints
Key Highlights & Results
Trained QLoRA adapters for Qwen2.5-0.5B/7B with full evaluation metrics
CLI reduces manual fine-tuning setup from days to a single command
Inference server integrates directly with MentorAI's RAG pipeline