MentorAI
RAG Platform
 Source Code
Overview
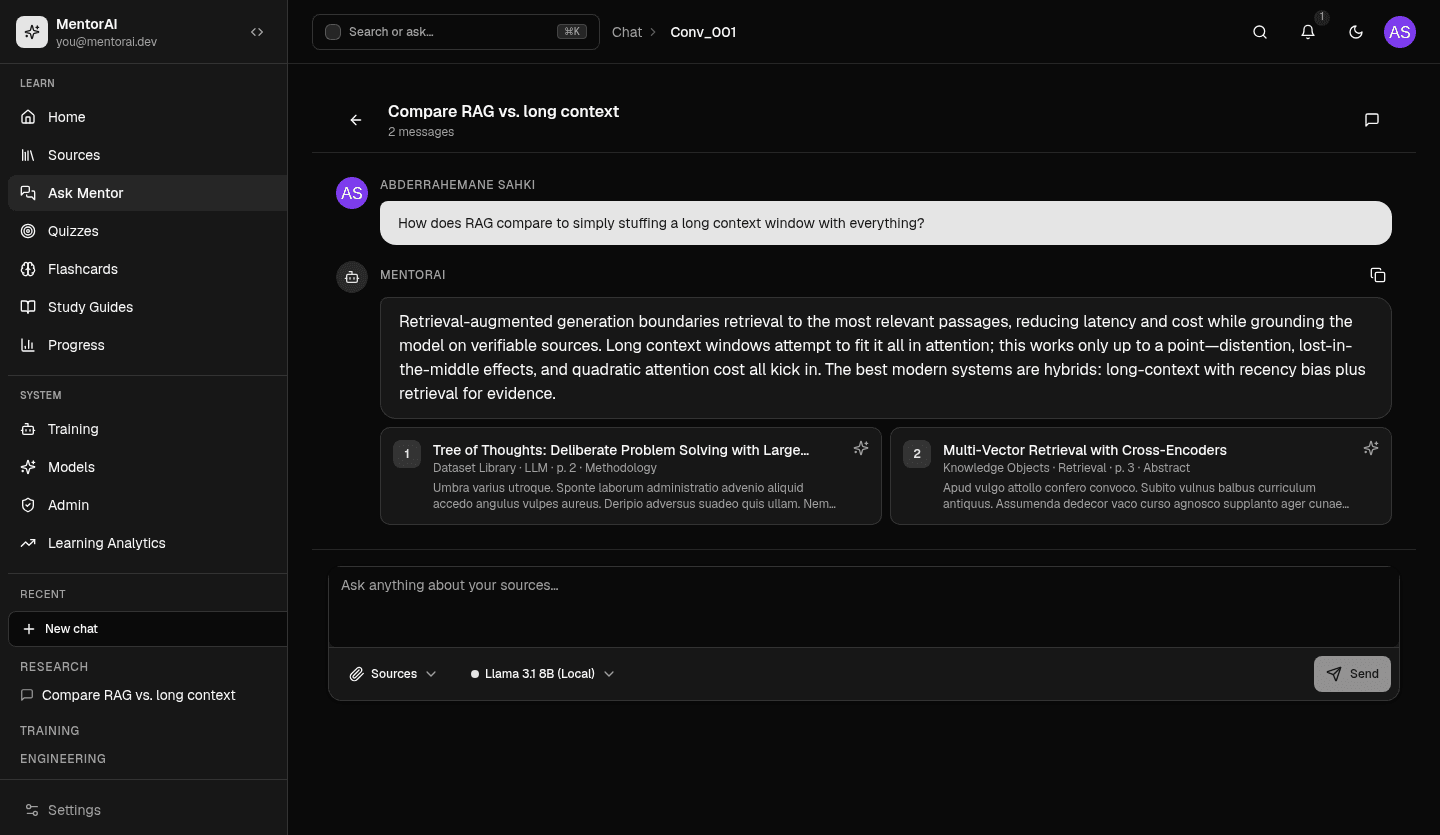
MentorAI is a full-stack RAG-powered learning platform comprising a Next.js 16 frontend, NestJS backend, and three Python FastAPI microservices (inference, training, processing). Users upload educational documents (PDFs, research papers) which are processed through a custom pipeline: extraction, cleaning, section splitting, chunking, and knowledge-unit creation. Embeddings are generated using BAAI/bge-small-en-v1.5 via sentence-transformers and indexed in FAISS. At query time the system retrieves the top-K most relevant chunks and passes them as context to a fine-tuned Qwen2.5-0.5B/7B LLM (trained via QLoRA using the mentorai-finetuning package), producing answers that cite their sources. The platform includes a standalone fine-tuning CLI (mentorai-cli) supporting SFT, LoRA, and QLoRA with hardware-aware auto-planning.
Problem & Solution
Technical learners waste hours searching docs and tutorials when they need a specific, contextual answer grounded in their actual study material.
Full-stack RAG platform with custom document processing, dense retrieval via sentence-transformers + FAISS, and a fine-tuned Qwen2.5 LLM for grounded, cited responses.
Architecture & Dataflow
Technical Stack & Implementation
AI / ML & Models
- Qwen2.5-0.5B/7B (QLoRA fine-tuned)
- sentence-transformers (BAAI/bge-small-en-v1.5)
- FAISS
- HuggingFace Transformers
- PEFT
- TRL
Backend & APIs
- NestJS
- TypeScript
- TypeORM
- FastAPI (3 microservices)
- Python
Frontend & UI
- Next.js 16
- React 19
- TypeScript
- Tailwind CSS
Data & Storage
- PostgreSQL
- Redis
DevOps & Infra
- Docker
- Swagger/OpenAPI
Technical Challenges & Solutions
Choosing optimal chunk size and overlap for technical documentation
Fine-tuning a small model (0.5B) to produce quality responses with RAG grounding
Coordinating 5 services (NestJS + 3 FastAPI + Next.js) in a coherent architecture
Key Highlights & Results
Full pipeline implemented: document processing → embedding → retrieval → fine-tuned generation
Trained QLoRA adapters with evaluation via ROUGE, BLEU, BERTScore, and LLM-as-Judge
Dataset of curated research papers (Attention Is All You Need, BERT, LLaMA, QLoRA, RAG, MLOps, CV)