VisualMind
Multimodal AI
 Source Code
Overview
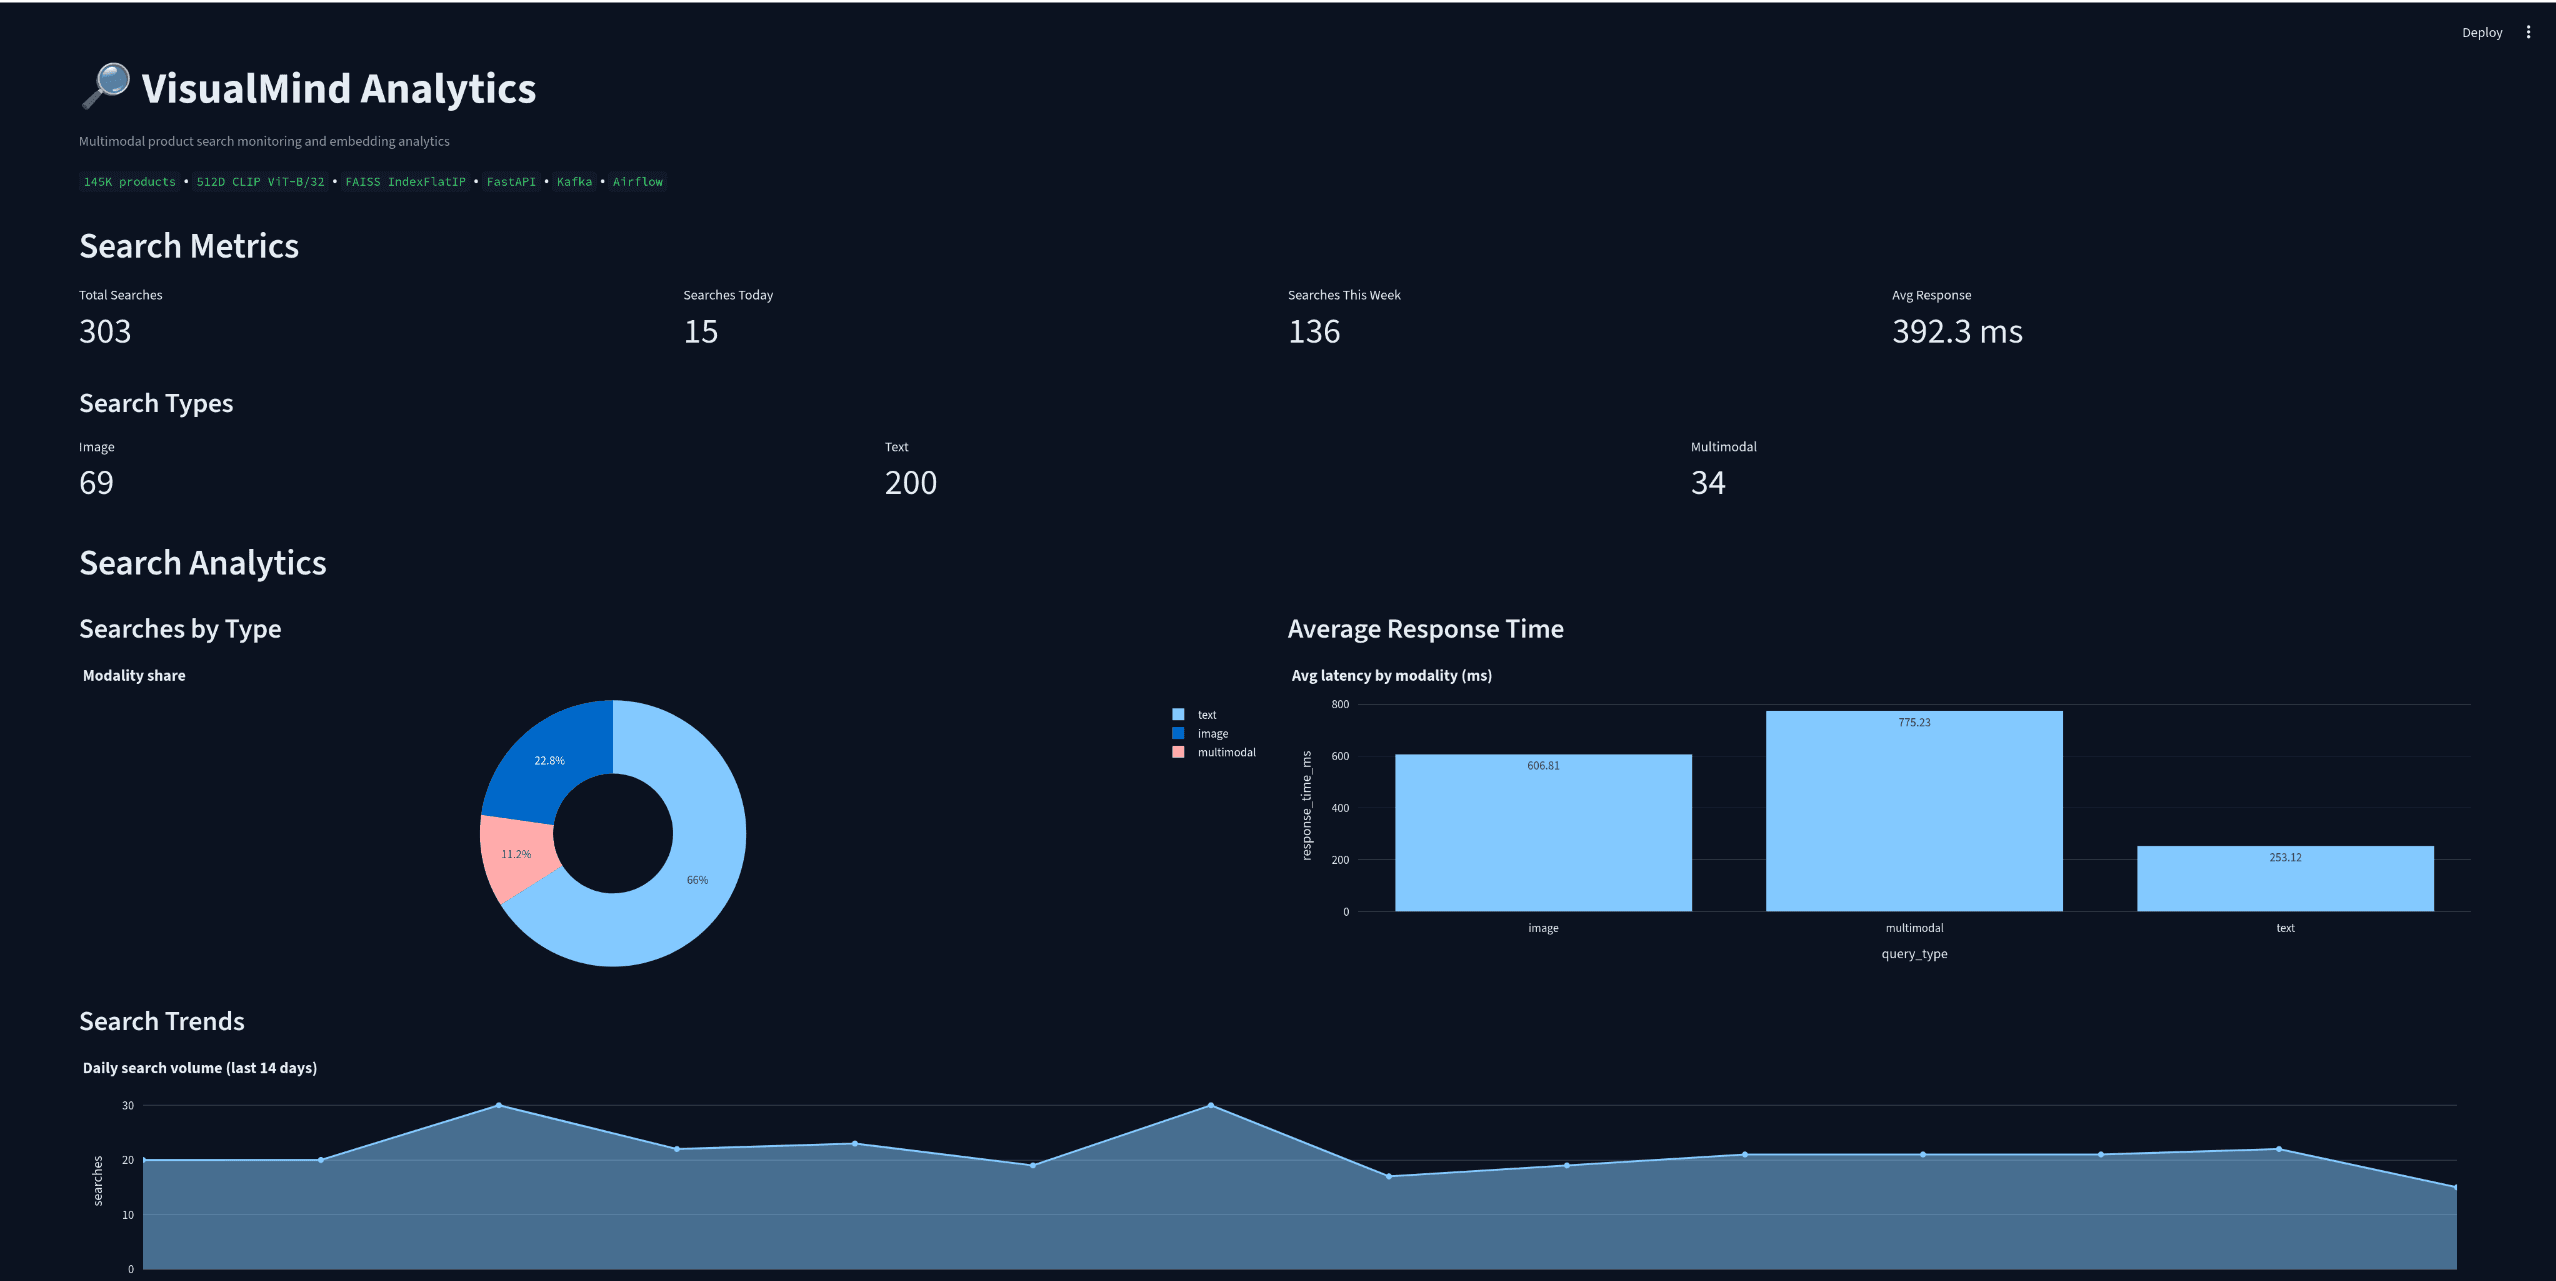
VisualMind is a multimodal product discovery engine built on the Amazon Berkeley Objects dataset (145,050 products). It encodes product images using OpenAI CLIP (ViT-B/32) into 512D embeddings stored in a FAISS IndexFlatIP vector index. Users can search by text description, upload a reference image, or combine both via weighted multimodal fusion (60% image / 40% text). The system also provides zero-shot CLIP classification for automatic product tagging (category, color, style), precomputed nearest-neighbor recommendations, and a Streamlit analytics dashboard with UMAP embedding visualization. Search events are published to Apache Kafka, and Apache Airflow schedules daily FAISS index rebuilds and recommendation refreshes.
Problem & Solution
Traditional text-based product search misses visual similarity — users can't find what they're looking for with words alone.
CLIP (ViT-B/32) embeddings + FAISS IndexFlatIP across 145,050 products, with zero-shot tagging, multimodal fusion, and offline recommendations.
Architecture & Dataflow
Technical Stack & Implementation
AI / ML & Models
- CLIP (openai/clip-vit-base-patch32)
- FAISS (IndexFlatIP)
- PyTorch
- HuggingFace Transformers
Backend & APIs
- FastAPI
- Python
- SQLAlchemy
- SQLite
Frontend & UI
- Streamlit
- Plotly
- UMAP
Data & Storage
- Pandas
- PyArrow
- Pillow
- NumPy
DevOps & Infra
- Docker
- Docker Compose
- Apache Kafka
- Apache Airflow
Technical Challenges & Solutions
Aligning text and image embedding distributions for consistent retrieval quality across modalities
Designing weighted multimodal fusion that balances visual and textual relevance
Building an event-driven pipeline (Kafka + Airflow) for continuous index freshness
Key Highlights & Results
Full pipeline: 8 steps from environment setup to Kafka+Streamlit analytics, all implemented
Index covers 145,050 products across 573 categories (~167 MB SQLite database)
Exact nearest-neighbor search via FAISS IndexFlatIP with sub-50ms latency